Note 1
Deep Dive into Deep Neural Networks
Neural networks (or neural nets) can be comprehended as a complex function that does not require manual feature engineering. Due to the high level of abstraction and automation in learning, neural nets are highly scalable. This note covers neural nets with mathematical interpretations and its application with Python.
1.1 Definitions and High Level Overview
As always, let’s get started with the fundamental terms and high level overview of what neural nets are. Before the introduction of neural nets, traditional models like linear/logistic regression and decision trees were used. The problem with traditional models is that you are likely required to manually adjust the features. With neural nets, the features are automatically engineered, making us to focus on the architecture.
1.1.1 High Level Architecture
To understand the high level architecture, consider the diagram below.
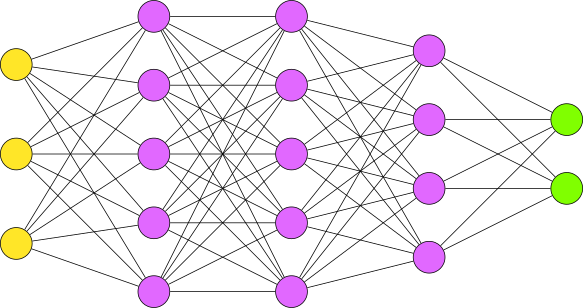
From now, let’s refer to the nodes as neurons.
Definition 1.1.1
Neurons are the fundamental unit in neural networks that process input into output with set of parameters.
From the diagram, the neurons are organized in to different columns. We call the columns layers.
Definition 1.1.2
The input layer is the layer that receives inputs for the neural network. Hidden layers are where the input data is processed with the learned parameters to extract information. The output layer is the final layer that represents the final prediction of the neural network.
In the diagram above, the input layer is represented as the layer with yellow neurons, hidden layers as the layers with purple neurons, output layer with the layer with green neurons. One of the advantages of neural network is that there is simply no limit, except computational limit. You can have unlimited amount of neurons in each layers and unlimited amount of hidden layers. The best neural net will be effectively structured in a way that there are sufficient neurons to learn from while avoiding overfitting and decreasing computational cost.
Definition 1.1.3
Connections are the links that connects the neurons with each other.
Just as our biological neurons are interconnected to each other, artificial neurons are connected to effectively extract the holistic feature from the input. Now it is worth noting that each neuron represents feature.
Here is a brief example. Say your neural net will classify handwritten numbers. The number \(9\) and \(0\) retains a similar feature. Both the numbers have a loop in the top. Therefore, in this scenario, the initial hidden layers may have similar features when categorizing the numbers.
In the past we used perceptrons, or neurons that uses step functions with binary output. However, modern multilayer perceptron (MLP) uses a more flexible neurons with continuous activation functions. Now let’s take a look at what individual neurons have with the diagram below.
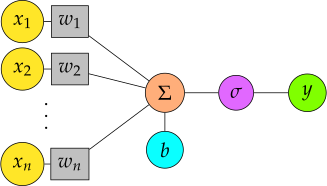
On the high level, an individual neuron takes the weighted sum of the previous layer with the trained parameter. Bias is then added to make the activations more flexible. Then, an activation function is used to determine the final activation of the neuron.
Definition 1.1.4
Activation of a neuron indicates the significance of a neuron, or presence of a feature from the input data. An activation function is a function that generalizes each activation and introduce non-linearity.
In the diagram above, the purple color represents the activation function and the green color represents the final output of the neuron. Here, non-linearity is important for generalization with activation function. The activation is represented as a linear weighted sum. However, for generalization, activation functions like ReLU (Sigmoid is considered outdated) are used.
Here, the superscript represents the layer and \(i\) identifies the neuron in the layer. The function \(\sigma \) is an activation function. It could be sigmoid, ReLU, tanh, and other activation functions.
1.1.2 Training
Inference is rather straight forward, but how do we “train” a model? Well, that’s what this part of the note is all about. There are few terminologies that we need to know, and I think we can discuss them as we go along.
Definition 1.1.5
Forward pass, also known as forward propagation, the process of generating output with input data.
Here, it is worth noting that forward pass is different from inference in a sense that the process of inference only applies to a complete trained model while forward pass also applies to models being trained.
Let’s discuss the definitions and underlying concepts in individual process after capturing the big picture. Generally speaking, the following diagram captures the training process.
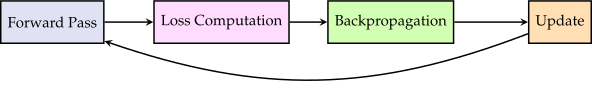
The first thing that we do after the forward pass is to calculate the loss.
Definition 1.1.6
Loss functions are algorithms that calculate the loss, or the performance of the prediction compared to the expected outcome.
There are many loss functions, but the two dominant functions are mean squared error (MSE) and cross-entropy (a.k.a. negative log-likelihood.) Generally, MSE is great for regression and cross-entropy excels at classification. Therefore, cross-entropy will commonly be used for LLMs for token predictions. Let’s take a look at each functions.
Following the convention, let \(\hat {y}_n\) and \(y_n\) be the prediction and the true value respectively. With MSE, the loss will be represented as \(\frac {1}{n} \sum (\hat {y}_i - y_i)^2\). The intuition behind this formula is we always want the loss to be positive as it is comfortable to think that our goal is to reduce the loss. If the loss is negative, it will be hard to apply this sense. That’s why we squared the difference. Now you might ask, why not absolute value? Indeed, there is a function Mean Absolute Error (MAE), but we like to square the values as it amplifies the loss. With cross-entropy, its a bit more complicated, but a simplified version would be \(\sum (-y_i \log (\hat {y_i}))\). More on cross-entropy will be discussed soon!
We know we can calculate the loss, but how do we actually improve the model with the calculated loss?
Definition 1.1.7
An optimizer is an algorithm that determines the necessary changes for model weights.
The dominant optimizer type is gradient descent with its variants like Adam, RMSProp, and SGD. There’s quite a bit of content for gradient descent for ML, so let’s discuss that in a separate section of the note.
1.1.3 Gradient Descent and Learning Rate
Before we implement the ideas and concepts above with code, I wanted to discuss gradient descent and training more in-depth to actually train our model. The partial derivatives and mathematical definition of gradient descent was discussed in the first note. Here, we will discuss about gradient descent specifically for ML.
Definition 1.1.8
Gradient descent as an optimizer represents how the weights and biases of a model are updated based on the gradients of the loss function.
You would typically start from a random position to move in the opposite direction of the gradient of the loss function. Before I introduce mathematical equation, here are two famous analogies of a ball rolling down the hill and finding a way in a foggy forest. Starting with the first analogy, consider the diagram below.

Imagine rolling a ball from the graph above. After some time, it will naturally fall into one of the pits. If we are lucky, we will find the global minimum, if not, we will fall into one of the local minima. To see how we roll a ball, consider two diagrams below.
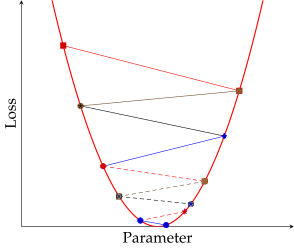
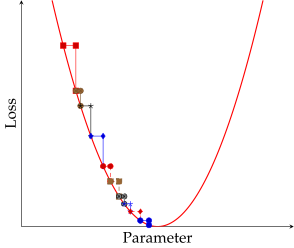
Taking a look at Figure 1.5, imagine your random point in the red square. Because the slope of the line tangent to the point in negative, you want to move to the right, or in positive direction. This time, your learning rate is high that the slope of the line tangent to the next landing position is positive. Therefore, you want to move to the left, which is the negative direction. After continuing this process over and over again while adjusting the learning rate, you will likely find the local minimum. In Figure 1.6, our learning rate is low. Despite being low, it will still lead to the local minimum. One thing to note is that you don’t want your learning rate to be low or high as you might need to train forever or overshoot. Learning rate is often denoted as \(\eta \), and we normally would adjust it with the gradient, which we will see in a bit. Of course in real training, we won’t be finding the slope of the tangent line as we do in the 2-dimensional plane. In higher dimension, we would find the gradient. Please refer to the first note for more information!
Another very popular analogy is foggy mountain analogy. Imagine you are in the top of the mountain, and its getting dark. You want to get to the lowest point as fast as possible. However, you can’t see anything beyond your local information because the mountain is very foggy. What would you do? We would find the gradient and multiply it with the learning rate to determine our step size. Then, with your local information, we would be able to approach the local minimum of the foggy mountain. Ideally, we should be hoping that we reach the lowest point and villages.
Now, before we continue for building our own neural net without machine learning libraries, let’s conclude the concepts by discussing different types of gradient descent and their effects.
Types of Gradient Descent
There are many types of gradient descents like Batch GD, Mini-batch GD, Stochastic GD, and Momentum-Based GD. However, the three major types are Batch Gradient Descent (BGD), Stochastic Gradient Descent (SGD), and Mini-batch Gradient Descent. On the high level, consider the following definitions.
Definition 1.1.9
With Batch Gradient Descent (BGD), each update will occur based on the entire training examples, which are often averaged. In contrast, Stochastic Gradient Descent (SGD) updates based on a single data point. Mini-batch Gradient Descent is the middle ground of BGD and SGD that it updates based on few data points like \(32\) or \(64\), usually in a power of \(2\).
From the sense, we can notice that the biggest difference in use case would be efficiency and accuracy. BGD is generally more accurate in each update than SGD as it is based on the entire data points. However, SGD is generally more efficient as it does not have to perform massive computations for each update to incorporate all the training examples. One interesting thing to note is that because SGD is “stochastic”, or more noisy, it is sometimes better at optimizing the updates as it moves more randomly than BGD.
When visualizing, we often consider the following diagram.
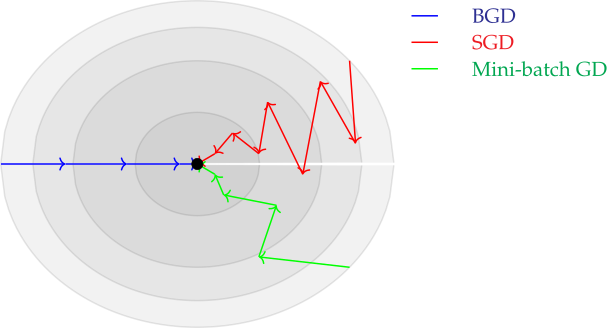
As you can see, BGD often heads straightly towards the minimum as the entire training examples are incorporated. Unlike BGD, SGD shows more random and noisy movement and often requires more updates to reach the local minimum. Finally, Mini-batch GD is like the movement in between those two. Its is some what random, but less noisy SGD that it often requires less updates.
Overall, this is what artificial neural nets are about. The pre-trained and inter-connected neurons work together to predict that output as a giant function. This giant function are composed of weights and biases, which are fine-tuned during the training process. During training, you calculate the loss and tweak the parameters to minimize the loss through gradient descent. You repeat the training process until your model learned well enough, but not too much to prevent overfitting. That’s pretty much it in the high level! For our next section, let’s discuss more on training and gradient descent before we actually try and build a neural network from scratch without ML libraries like PyTorch and TensorFlow.
Congratulations! We just finished the high level overview of what neural nets are and what vanilla neural nets are composed of. Before we actually try and implement the concepts with Python to build a vanilla neural net without machine learing libraries like PyTorch and TensorFlow, let’s take a look at mathematical equations to write them in code.